AI Evaluation Beyond Accuracy: A Practical Quality Framework
Apple Silicon Compatibility: ARM, x86 and Virtual Machines
A product team can conduct dozens of user interviews, collect hundreds of survey responses, and build sophisticated analytics dashboards while still lacking the evidence needed to make its next product decision. Research activity can look impressive on a project timeline, but the amount of research conducted tells us surprisingly little about whether the team has reduced the uncertainty that actually matters.
This is why I believe UX research methods should be selected according to decision risk, not professional habit. The first question should not be whether the team prefers interviews, usability testing, surveys, or analytics. It should be what decision the organization needs to make, what could happen if that decision is wrong, and which type of evidence could meaningfully change the outcome.
Consider two situations. A team is adjusting the wording of a reversible settings label. Another team is replacing the navigation architecture of an enterprise platform used by people with different responsibilities and accessibility requirements. Both decisions involve user experience, but they do not justify the same research investment, sampling strategy, or level of certainty.
I would approach those situations differently even if the organization had the same researchers, the same budget, and access to the same research tools. In the first case, a focused usability assessment may be sufficient to identify the most important ambiguity. In the second, the team may need to understand user roles, task behavior, information architecture, performance across relevant groups, and the consequences of making the wrong structural choice.
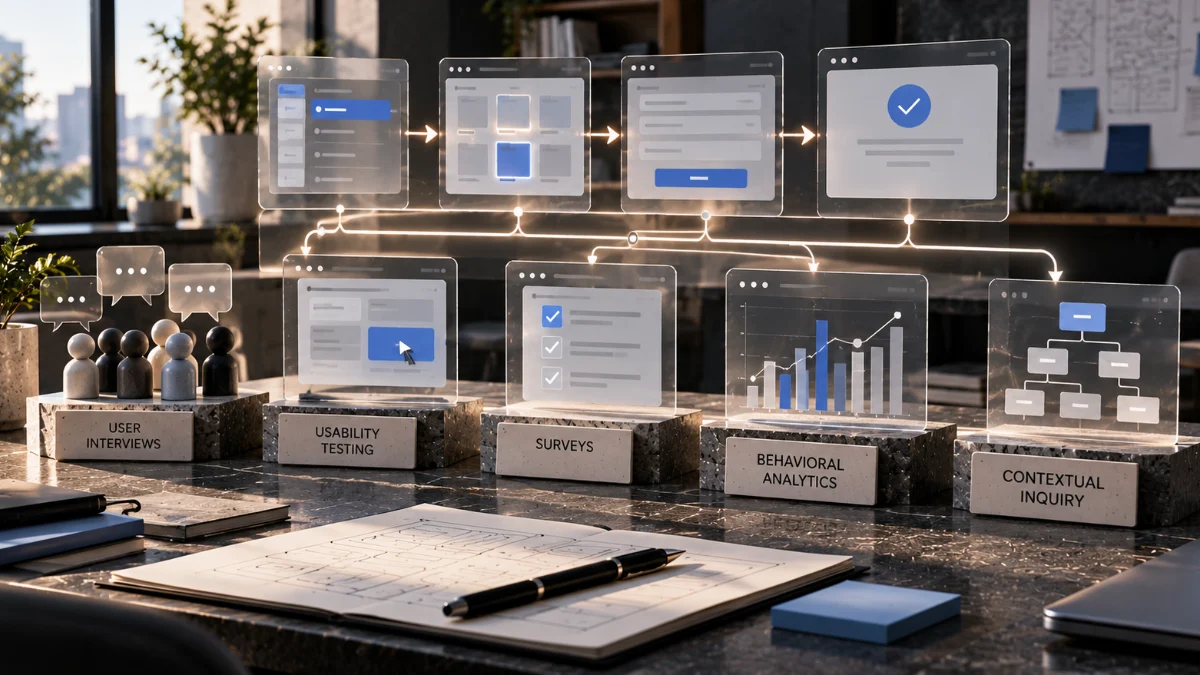
My central argument is that UX research strategy should connect methods to decisions through evidence. Interviews can reveal experiences that analytics cannot explain. Usability testing can expose behavioral problems that participants may not predict in an interview. Surveys can estimate attitudes or reported experiences under appropriate sampling conditions. Behavioral analytics can reveal patterns in recorded usage without necessarily explaining their causes. These are complementary forms of evidence, not interchangeable ways to confirm the same conclusion.
In this article, I will examine the established methodological distinctions behind user research and introduce a practical Decision-Risk Research Fit Framework. The framework is my proposed synthesis for choosing UX research methods based on the consequences of a wrong decision, the uncertainty that remains, and the evidence each method can reasonably provide. Its illustrative scenarios are hypothetical; they are not reports of completed client research or measured product outcomes.
Decision Brief: Choose Research Based on the Decision at Risk
The problem: Product teams sometimes select familiar or convenient research activities without establishing whether those activities can answer the questions that influence the next consequential decision.
The recommended approach: Define the decision, identify the cost and reversibility of being wrong, determine the missing evidence, and select one or more research methods capable of addressing that uncertainty.
The expected value: A more defensible connection between research investment, user evidence, and product decisions, with fewer opportunities to confuse a persuasive finding with an adequately supported conclusion.
The limitation: Choosing an appropriate method does not guarantee high-quality evidence. Recruitment, sampling, task design, measurement, interpretation, accessibility, and organizational decision-making remain essential.
Why UX Research Methods Should Be Chosen by Decision Risk
The standard way to introduce UX research methods is to describe what each method does. Interviews help researchers understand experiences and motivations. Usability testing reveals difficulties during tasks. Surveys gather structured self-reported information. Analytics describes recorded usage behavior. These distinctions are necessary, but they are not yet a complete decision-making process.
A method becomes appropriate when its evidence addresses a question the team needs answered. If the decision is whether an existing workflow is understandable, asking people what they think about its visual design may be less informative than observing them attempting the workflow. If the decision concerns how common a reported difficulty is among a defined population, a handful of interviews may expose the difficulty without providing a defensible prevalence estimate.
Nielsen Norman Group’s When to Use Which User-Experience Research Methods, reviewed in July 2026, organizes methods along three established dimensions: attitudinal versus behavioral, qualitative versus quantitative, and the context in which participants use the product. It also describes their relevance at different stages of product development.
I find that framework valuable because it clarifies what different methods can reveal. My additional proposal is to place a decision-risk question before method selection. Rather than beginning with the catalog of available techniques, begin by identifying what the organization is about to commit to and what evidence would make that commitment more defensible.
The Consequence of Being Wrong Changes the Research Requirement
Decision risk is not simply a synonym for project size. A small interface change can be consequential if it affects authorization, accessibility, or an irreversible user action. A substantial visual adjustment may carry relatively little risk if it can be rolled back easily and does not alter essential behavior.
I would examine three characteristics of the proposed decision. The first is consequence: who might be harmed or disadvantaged by a wrong choice, and what would that mistake cost? The second is reversibility: how difficult would it be to correct the decision after implementation? The third is evidence uncertainty: how much of the decision currently depends on untested assumptions?
These dimensions should be considered together. A low-cost, reversible design adjustment with clear evidence may justify a small formative study. A hard-to-reverse restructuring supported mainly by stakeholder opinion may justify several complementary investigations and explicit acknowledgment of remaining uncertainty.
This does not mean every important decision requires expensive research. Existing evidence, well-designed small studies, and focused methods can be valuable. The important consideration is whether the planned research offers sufficient decision-relevant information for the risk being accepted.
Research Activity Is Not the Same as Decision Confidence
Teams can confuse the volume of research artifacts with the quality of the underlying evidence. A large survey may be poorly sampled. An interview study may recruit participants who do not perform the relevant task. An analytics dashboard may track clicks without establishing whether users achieve their goals. A polished usability report may document interface problems while leaving the intended product decision unanswered.
I would rather see a team conduct one narrowly defined investigation whose findings can change a decision than several research activities that only confirm what stakeholders already expect.
The GOV.UK guidance on planning user research recommends defining research questions, challenging unsupported assumptions, and choosing activities that provide reliable answers for an appropriate investment of effort. This supports a practical principle: research planning should begin with what needs to be learned, not with which method a team happens to be accustomed to running.
Understand the Evidence Behind Different UX Research Methods
Before choosing a research method, I would make three distinctions explicit: what people say versus what they do, how a problem works versus how frequently it occurs, and whether behavior takes place in a realistic or constructed setting. These distinctions do not produce a rigid hierarchy of methods. They describe the kinds of claims that each approach is better equipped to investigate.
Attitudinal Research Versus Behavioral Research
Attitudinal research examines what people report about their opinions, experiences, preferences, expectations, and motivations. Behavioral research examines what people actually do. Both can be valuable, but the information they produce should not be treated as equivalent.
An interview participant may report that a product is easy to use while struggling to complete an essential task during observation. Another participant may describe frustration but complete the task effectively. Neither contradiction automatically makes one source invalid. It indicates that perceived experience and observable task behavior are different aspects of the user experience.
Nielsen Norman Group’s Attitudinal vs. Behavioral Research in UX explains how self-reported attitudes and observed behavior can complement one another. Qualitative usability studies and contextual inquiry, for example, may capture both what participants do and what they report about their actions.
When choosing UX research methods, I would therefore ask whether the decision depends primarily on a belief, expectation, or perception, or on successful completion of a task. If the team needs to understand why users perceive a service as untrustworthy, interviews may be important. If it needs to know whether people can complete an authorization workflow without errors, observing realistic task behavior is essential.
Qualitative UX Research Versus Quantitative UX Research
Qualitative UX research is particularly useful for discovering problems, understanding behavior in context, exploring explanations, and identifying how an experience might be improved. Quantitative UX research can help estimate measurable characteristics such as task completion rates, time on task, or the prevalence of specified responses, provided the research design supports the intended inference.
The familiar distinction between why and how many is useful, but it should not be interpreted too literally. Qualitative research can reveal what happens, how it happens, and the different explanations participants offer. Quantitative methods can test carefully specified relationships and compare outcomes. The critical difference is the nature of the evidence and the claims that can reasonably follow from it.
A qualitative usability study may reveal that several participants misinterpret the same control. That is an actionable design finding. It does not automatically establish the percentage of all users who will experience the difficulty. A large analytics dataset may show that a substantial share of recorded sessions ends at a particular step. That observation does not, by itself, explain why users stop.
I would avoid choosing quantitative UX research simply because executives want numbers. The team first needs to determine which quantity it wants to estimate, for which population, and with what acceptable uncertainty. Numbers generated from an inappropriate sample can be less useful than carefully bounded qualitative evidence.
Natural Usage, Task-Based Testing, and Decontextualized Research
The environment in which participants encounter a product affects what a study can reveal. Naturalistic observation may expose interruptions, organizational practices, workarounds, and dependencies that are difficult to reproduce in a controlled session. Task-based usability testing allows researchers to examine defined interactions under more consistent conditions. Surveys or interviews may gather information without requiring participants to use the product during the research activity.
Each context creates advantages and limitations. A controlled task can make differences between designs easier to inspect, but it may exclude competing demands present during everyday work. Natural usage can reveal authentic complexity, but uncontrolled circumstances may make causal interpretation difficult.
For high-impact decisions, I would ask whether the research environment preserves the conditions responsible for the problem. Testing an enterprise approval flow in isolation may miss the fact that real employees must switch between several systems, obtain information from colleagues, and wait for permissions before they can complete their work.
Comparing UX Research Methods by the Questions They Answer
The following comparison is not a universal ranking of techniques. It is a method-selection reference for matching a decision question with evidence. The most appropriate method depends on what the product team needs to establish, the relevant user population, the maturity of the product, and the cost of drawing the wrong conclusion.
| Research method | Useful decision question | Evidence strength | Important limitation |
|---|---|---|---|
| User interviews | What experiences, expectations, and constraints might explain the reported problem? | Rich accounts of specific experiences, goals, and reasoning. | Self-report and recall cannot alone establish actual behavior or population prevalence. |
| Qualitative usability testing | Where and how do users struggle with a defined interface task? | Direct observation of task behavior and specific usability breakdowns. | Small exploratory samples do not establish precise failure prevalence. |
| Surveys | How are specified attitudes or reported experiences distributed across a target population? | Structured self-reported responses, potentially supporting estimates. | Sampling, wording, nonresponse, and recall can distort conclusions. |
| Behavioral analytics | What usage patterns and recorded outcomes appear in the current product? | Observed events across instrumented users and sessions. | Tracking gaps, selection effects, and missing context limit causal explanation. |
| Contextual inquiry | How does the task operate within the user’s real environment? | Observed workflows, interruptions, workarounds, and environmental constraints. | Access restrictions and selected contexts may limit generalization. |
| Tree testing | Can users locate information within a proposed navigation structure? | Task-based evidence about findability independent of visual interface design. | Does not validate the complete visual or interactive experience. |
| Card sorting | How do participants group or interpret content concepts? | Signals about mental models and candidate information structures. | Preferred groupings do not prove users can successfully navigate a resulting design. |
| Quantitative usability testing | What task-success, time, or error outcomes can be estimated for a defined population? | Comparable task metrics under a specified sampling and study design. | Requires appropriate sample planning, measurement, and uncertainty reporting. |
| Randomized A/B testing | Which tested variant produces a different measured outcome under the experiment conditions? | Comparative evidence about the effects of the tested intervention when the experiment is valid. | Does not automatically explain the mechanism or generalize beyond the tested context. |
The Nielsen Norman Group overview of quantitative UX research methods distinguishes several of these techniques by their purpose, cost, collection requirements, and usage context. Its classifications provide a useful starting point, but I would still evaluate method fit against the particular product decision.
When User Interviews Are the Right Starting Point
I would select user interviews when the team needs to understand experiences, motivations, expectations, or the context behind an unclear problem. Interviews are particularly useful early in discovery when the organization knows that something is difficult but cannot yet describe the underlying mechanisms with confidence.
For example, users may say that reporting is stressful. An interview can explore a recent reporting task, the information they needed, how they obtained it, which interruptions occurred, and what they did when information was missing. That evidence can help distinguish an interface problem from a process, data, or organizational constraint.
However, I would not ask participants to predict with certainty how they would behave using a future feature and then treat their answers as observed behavior. Hypothetical preference has value as a signal, but it needs to be interpreted within its limits.
When Usability Testing Is the Better Choice
I would choose usability testing when a product team needs to inspect how people attempt a task using an existing interface or prototype. Watching users work reveals hesitation, misinterpretation, unsuccessful paths, and recovery behavior that may not emerge from a discussion alone.
Usability testing is especially valuable for decisions about navigation, forms, task sequences, error handling, content clarity, and interaction behavior. It is less suitable as the only method when the team must estimate a population-wide rate, understand complex longitudinal behavior, or investigate an organizational process that cannot be reproduced in a test setting.
The study should use realistic tasks and appropriately recruited participants. A scenario that tells participants exactly which control to use can conceal the discoverability problem the team needs to investigate. Likewise, testing with employees who already understand the design may provide a misleading picture of how unfamiliar users experience it.
When UX Surveys Can Support the Decision
UX surveys can help investigate structured questions about attitudes, expectations, reported experiences, and perceptions across relevant groups. They can be particularly useful when earlier qualitative research has clarified which concepts and response options matter.
But a survey is not automatically representative because it contains many responses. A large convenience sample can still systematically exclude important users. Question wording can also influence the answers, particularly when participants are asked to agree with a proposed solution rather than describe their experience.
I would use surveys when the decision genuinely depends on self-reported information and when the organization can recruit an appropriate sample. If the critical question is whether users can successfully complete a task, I would prioritize behavioral evidence rather than interpreting survey confidence as proof of task competence.
When Behavioral Analytics Provides the Most Useful Signal
Behavioral analytics is useful when the product already records relevant interactions and the team needs to understand their distribution over time. It can reveal where users abandon a sequence, how often a workflow is entered, how paths differ among defined segments, or whether a known outcome changes after an intervention.
The quality of the evidence depends on instrumentation. An event called task_completed may describe a button click rather than successful completion of a meaningful user goal. A session ending at a particular screen does not necessarily mean the user was confused; the user may have finished what they intended to do.
I would therefore examine event definitions, missing observations, identity assumptions, and possible confounding factors before drawing a conclusion. Analytics is often an excellent way to identify where further research is warranted, but it does not independently explain every pattern it reveals.
When Specialized Methods Are Necessary
Some decisions require more specific UX research methods than interviews, surveys, and general usability testing. If a team is restructuring navigation, tree testing can investigate findability, while card sorting may provide evidence about conceptual grouping. If workflow behavior changes across days or weeks, a diary study may reveal patterns that a single session cannot capture. If the question concerns the effect of a specific released design change, a properly designed experiment may support a causal comparison.
The decision question should determine whether such methods are justified. Specialized techniques should not be introduced simply because they are available or because a project has reached a conventional research phase.
The Decision-Risk Research Fit Framework
I propose the Decision-Risk Research Fit Framework to help product and UX leaders translate a consequential decision into a defensible research approach. It is an original editorial synthesis of established user research methodology and risk-based decision reasoning, not a formally validated industry standard.
The framework has four connected elements: decision, exposure, uncertainty, and evidence fit. Together, they determine which research activity is worth performing next and what the team can reasonably conclude from its results.
1. Define the Decision Before Selecting UX Research Methods
Begin with a decision statement, not a method request. “We need to run interviews” is an activity proposal. “We need to determine whether administrators can reliably locate and approve access requests after the proposed navigation change” is a decision-relevant question.
Then identify what changes depending on the answer. Will the team retain the current architecture, reorganize navigation, modify terminology, delay release, or conduct further investigation? If the research cannot influence any meaningful action, its immediate decision value may be limited.
I would also distinguish the person experiencing the problem from the person authorizing the decision. A product director may approve a redesign, but administrators, support staff, and operational users may encounter different consequences. Their evidence should be gathered and interpreted according to their actual roles.
2. Evaluate the Exposure Created by a Wrong Decision
Decision exposure combines the seriousness of a wrong choice with its practical consequences. The team should consider potential user harm, accessibility barriers, task failure, operational disruption, implementation cost, and the difficulty of changing direction.
I would use qualitative categories such as limited, material, or critical exposure only when the team can explain what those categories mean in its context. A numerical risk score can be useful in some organizations, but arbitrary weights can create false precision and conceal risks that should not be traded away.
A design decision affecting a decorative component may have limited consequences. A decision changing navigation across a role-based enterprise platform may have material consequences. A decision affecting access to essential information, financial actions, or safety-sensitive services may create critical requirements that cannot be treated as ordinary usability preferences.
Reversibility matters too. A localized wording change can often be corrected quickly. A major information architecture change may require migration, training, documentation updates, changes to saved links, and coordination across teams. The research effort should reflect that difference.
3. Identify the Uncertainty That Could Change the Decision
The team must determine what it already knows and what remains unsupported. Is the principal uncertainty about user motivation, observed task behavior, the frequency of a problem, differences among user groups, or the effect of a proposed intervention?
These uncertainties require different evidence. Interviews can help explain experiences and contextual constraints. Task testing can expose interaction breakdowns. Quantitative research can estimate a defined outcome under suitable conditions. Randomized experiments may support conclusions about a specific intervention when their assumptions and implementation are sound.
Rather than asking which UX research methods are most powerful in general, I would ask which missing observation would most change the next decision. That question reduces the risk of conducting a familiar study that leaves the central uncertainty untouched.
4. Select the Method and Define What It Can Establish
Only after the decision, exposure, and uncertainty are clear would I select the research method. The method must be capable of producing evidence relevant to the question, be feasible under the available constraints, and permit claims that are appropriately bounded.
For a low-risk decision, an exploratory usability test may reveal enough to support a reversible improvement. A high-risk navigation redesign might justify contextual research, representative task testing, segmented quantitative measurement, and targeted accessibility evaluation. The need for multiple methods follows from the evidence gaps, not from a fixed research quota.
I would define the expected output before beginning the study. That output may be a list of observed usability failures, an explanation of a workflow constraint, a statistical estimate with uncertainty, or a comparison between design alternatives. It should not promise a stronger conclusion than the method can provide.
| Decision exposure | Principal uncertainty | Possible research approach | Decision boundary |
|---|---|---|---|
| Limited and reversible | Whether a control label is understood. | Focused qualitative usability testing with relevant users. | Identify misunderstandings; do not infer population prevalence from a small study. |
| Material | Why users abandon an important workflow. | Behavioral analytics followed by contextual interviews or task observation. | Separate observed abandonment from an explanation of its cause. |
| Material and difficult to reverse | Whether a new navigation hierarchy supports different user roles. | Role-specific task analysis, tree testing, and appropriately scoped usability studies. | Evaluate each relevant role rather than assuming one group represents all users. |
| High-impact comparative choice | Which implemented option improves a defined outcome. | Controlled comparative testing or a suitable randomized experiment. | Limit causal claims to what the study design and data actually support. |
| Critical accessibility or task access | Whether users with relevant access needs can complete essential work. | Accessibility assessment, assistive-technology testing, and appropriate user research. | Do not substitute an automated scan or an aggregate success score for task accessibility. |
The framework does not mean that a critical decision always requires the largest possible study. It means that decision-makers must justify why the available evidence is adequate for the consequences they are accepting. When evidence is insufficient, the responsible choice may be to narrow the release, investigate a specific uncertainty, or preserve the existing experience until the risks are better understood.
A Hypothetical UX Research Plan for an Enterprise Admin Platform
Consider a hypothetical enterprise platform used by administrators, department managers, and support staff. The organization wants to reorganize its navigation because stakeholders believe that users have difficulty finding important administrative functions. A proposed redesign would replace the existing menu structure with a new hierarchy organized around functional areas.
The feature request appears reasonable, but several questions remain. Which users cannot find which functions? Is the problem caused by category labels, permission-based visibility, excessive menu depth, unfamiliar terminology, or workflows that cross organizational responsibilities? Does the proposed navigation solve those difficulties, or merely reorganize them?
This scenario is an illustrative research design, not a report of a completed study. No real participants, usage recordings, analytics exports, or measured task-success rates are being presented.
First, Understand Why the Decision Is Consequential
Replacing enterprise navigation can affect users who perform different tasks and have different permissions. Administrators may need configuration and user management functions. Managers may focus on approvals and operational reports. Support staff may need troubleshooting and case histories. A new hierarchy can make one group’s work easier while making another group’s essential functions harder to locate.
In addition, navigation decisions can create technical and organizational dependencies. Saved links, help documentation, onboarding materials, role definitions, training resources, and automated workflows may reference the existing structure. The team should understand those dependencies before treating the redesign as a cosmetic change.
Because the decision affects several user groups and may be costly to reverse, I would not rely exclusively on a small set of general preference interviews.
Select UX Research Methods for Different Evidence Gaps
I would first examine existing support records and appropriately instrumented analytics, if those records are available and relevant. The objective would be to identify which functions generate repeated assistance requests, which navigation paths show unusual friction, and where evidence is missing. These observations would generate research questions rather than automatically establish the cause of the difficulty.
Next, I would conduct contextual interviews or task observation with participants representing the relevant roles. I would ask them to demonstrate recent administrative work where feasible, describe how they locate functions, and explain workarounds or interruptions. The goal would be to identify the real task context and distinguish navigational problems from access-control or organizational issues.
If the team has two candidate information architectures, I would consider tree testing with role-specific task scenarios. The study would examine whether users can identify the appropriate path to a target function without relying on the visual design of the complete interface.
Finally, I would examine the proposed interface through usability testing, including representative critical tasks and relevant accessibility considerations. Tree testing could support a structural decision, but it would not establish that the completed interface is understandable, operable, or accessible in realistic use.
The actual sample sizes, recruitment criteria, and quantitative measurement plan would need to follow the questions and decisions involved. I would not claim that a single participant count is sufficient for every role, method, and statistical objective.
Define the Claims Each Study Would and Would Not Support
| Research activity | Evidence sought | Unsupported conclusion to avoid |
|---|---|---|
| Analytics and support review | Recorded navigation behavior and recurring reported difficulties. | Assuming a specific interface cause without examining the workflow. |
| Contextual inquiry | Role-specific tasks, terminology, environmental constraints, and workarounds. | Assuming observed participants represent all users or every organizational context. |
| Tree testing | Whether participants can find target functions within a proposed hierarchy. | Claiming that the full visual interface is usable or accessible. |
| Usability testing | Task paths, errors, hesitations, comprehension, and recovery behavior. | Reporting precise population-wide success rates from a small exploratory sample. |
| Targeted accessibility testing | Barriers affecting essential tasks under relevant input and assistive technologies. | Claiming complete accessibility from one tool or one limited test. |
Once the evidence is available, the team could compare alternative designs against the requirements of each user group. The correct conclusion might support the proposed hierarchy, recommend a more limited change, or reveal that the main difficulty lies outside navigation itself.
The important point is that the research plan creates opportunities for the original proposal to be challenged. A study that can only confirm the proposed redesign is not a sufficient investigation of the decision.
Research Triangulation Should Reduce Decision Uncertainty
Using multiple UX research methods is often described as triangulation. At its best, triangulation examines an important question from different perspectives so that the limitations of one method can be better understood through evidence from another.
Nielsen Norman Group’s guidance on research triangulation explains how combining methods can strengthen understanding and why the significance of a decision should influence how much corroborating evidence is sought.
I agree with the principle, but I would avoid turning triangulation into a requirement to run three studies simply because they have different names. Two weak methods with the same underlying sampling problem may not provide meaningful independent confirmation. A survey and an interview can both reproduce the same self-reporting bias if participants are recruited from the same narrow group and asked essentially the same leading questions.
Useful triangulation requires understanding which limitations differ among the selected methods. Analytics may show a pattern at scale but provide little explanatory context. Observation may reveal a mechanism but involve a small number of participants. Together, they can produce a better-founded interpretation when their populations, definitions, and time periods are sufficiently comparable.
When UX Research Findings Disagree
Suppose survey respondents report that navigation is straightforward while usability participants repeatedly struggle to find an important administrative function. The results do not necessarily contradict each other. Respondents may be expressing overall satisfaction, while task testing examines one specific activity. They may also represent different groups, levels of experience, or usage conditions.
Before choosing which evidence to trust, I would inspect the exact construct measured, participant selection, task context, measurement period, and wording of the research question. The disagreement may reveal a missing distinction rather than a failed method.
This is an important boundary for UX research strategy: research triangulation should not become a process of averaging incompatible findings into a single number. The objective is to understand what each source establishes and where the evidence remains incomplete.
When Additional Research Stops Being Valuable
Teams can spend too little time researching consequential decisions, but they can also continue collecting evidence after the next decision is already sufficiently informed. I would define a stopping condition around the uncertainty that matters, not around the number of sessions completed.
If several plausible explanations remain and lead to substantially different design decisions, additional research may be justified. If the remaining disagreement is unlikely to alter a low-risk, reversible choice, the team may reasonably proceed while monitoring the outcome.
This requires judgment. There is no universal rule stating that a certain number of interviews, survey responses, or usability tests automatically makes a decision safe. The amount and kind of evidence must be proportionate to the intended inference and the consequences of being wrong.
Sample Size and Research Validity: What Small Studies Can Tell You
One of the most persistent sources of confusion in UX research is the assumption that a small study is either sufficient for everything or worthless for serious decisions. Both positions ignore the purpose of the research.
Small qualitative usability studies can reveal significant interaction problems and help teams understand how participants approach tasks. They are not designed to provide precise estimates of how frequently every problem occurs across an entire population.
Nielsen Norman Group’s discussion of qualitative usability study sample sizes explains why small iterative studies can be productive for discovering usability issues. Its separate guidance on quantitative usability sample sizes addresses why estimating population metrics generally requires larger samples and an understanding of confidence intervals.
I would not translate those recommendations into a universal participant quota. Different user groups, task variability, risk levels, sampling methods, and desired precision can lead to different requirements.
Distinguish Problem Discovery From Prevalence Estimation
Suppose a qualitative usability study finds that several participants misunderstand a destructive action. That observation can justify further investigation or a design correction, especially when the consequence of an error is significant.
However, the team should not automatically turn the observation into a claim that the same percentage of all users would make the mistake. A selected exploratory sample is not equivalent to a representative probability sample.
If a product decision depends on estimating a failure rate, the team needs an appropriate quantitative design, a defined population, a clear outcome measure, and an honest account of uncertainty. The appropriate sample size depends on those conditions rather than on a familiar number repeated across projects.
Research Validity Depends on Who Is Represented
Sample size is only one dimension of research quality. A large sample of the wrong participants can create misleading confidence. For a professional enterprise platform, recruiting general consumers who have never performed administrative work may produce observations that are difficult to apply to the target environment.
I would prioritize characteristics that materially affect the task, including user role, experience level, relevant abilities, workflow frequency, and operational context. If the product supports different languages or significantly different organizational practices, those differences may need explicit investigation.
The research report should state who participated, how they were recruited, which groups were excluded or underrepresented, and how those limitations affect the conclusions. This information allows decision-makers to understand where the evidence can be applied.
Confidence Should Be Explained, Not Manufactured
Quantitative research can communicate sampling uncertainty through confidence intervals or other appropriate statistical methods. But calculations cannot eliminate bias caused by poor recruitment, invalid tasks, incomplete measurement, or mismatched populations.
Nielsen Norman Group’s guidance on confidence intervals in UX emphasizes that the usefulness of a numerical estimate depends on its precision and the underlying study conditions.
I would therefore avoid reporting a highly specific success percentage when the study cannot support that precision. A bounded qualitative finding may be more responsible than a numerical claim whose apparent certainty exceeds the evidence.
Accessibility and Inclusion Change Which Research Methods Are Adequate
Decision risk becomes particularly important when a product change can prevent some users from completing essential tasks. A design may appear successful under routine usability testing while creating substantial barriers for people who use different input methods, assistive technologies, or accessibility settings.
The W3C Web Accessibility Initiative’s evaluation guidance explains that tools alone cannot determine whether a website is accessible; knowledgeable human evaluation is necessary. Automated checks can identify many important issues, but they cannot fully establish how an interface works for people in realistic tasks.
When accessibility is relevant to the decision, I would combine appropriate technical assessment with task-oriented investigation. Keyboard navigation, focus behavior, semantic structure, accessible names, error feedback, and compatibility with relevant assistive technologies may require different checks.
I would also avoid assuming that one participant with a disability represents everyone with a similar diagnosis or access need. Research recruitment and interpretation should recognize differences in experience, technology, context, and individual preferences.
An inclusive UX research plan should identify which users and tasks are critical, what barriers the research is intended to detect, and what cannot be established from the chosen sample. If the intended product must satisfy defined accessibility requirements, those requirements should remain independent of general satisfaction or conversion metrics.
Turning UX Research Findings Into Defensible Product Decisions
The value of UX research methods should ultimately be assessed through the decisions they inform. A study can produce valid observations without producing a sufficient basis for a broader conclusion. Researchers and decision-makers need to distinguish findings, interpretations, recommendations, and commitments.
A finding describes what was observed or reported under defined conditions. An interpretation proposes what that evidence means. A recommendation identifies a potentially useful action. A product decision determines whether the organization will take that action, investigate further, or accept the existing limitations.
When those layers are mixed together, recommendations can appear more certain than their evidence allows. For example, observing that participants repeatedly return to the main menu may support a finding about navigation behavior. It may suggest difficulty locating content, but that explanation should be investigated rather than presented automatically as fact.
Use a Compact Research Decision Record
For consequential design choices, I would retain a short record connecting the decision to its evidence. This is not intended to replace research reports, interview notes, or product documentation. It is a concise artifact that explains why the team considered the evidence sufficient for the action it selected.
| Field | Illustrative entry |
|---|---|
| Decision | Whether to replace the enterprise administration navigation hierarchy. |
| Exposure | Potential disruption to critical tasks across multiple permission-based roles. |
| Current uncertainty | Whether the primary difficulty involves labels, hierarchy, permissions, or task organization. |
| Selected research | Role-specific task observation, tree testing, and relevant usability and accessibility assessment. |
| Evidence required | Observed paths, comprehension problems, task outcomes, and limitations by relevant user group. |
| Decision options | Retain the existing structure, make a limited change, investigate further, or proceed with a broader redesign. |
| Disconfirmation | Evidence that the primary difficulty originates outside the assumed information architecture. |
The record should remain honest about what the research has not yet demonstrated. It should not contain invented success rates, participant quotes, or claims that a proposed solution has already been validated.
Research Leadership Is Also About Saying What the Evidence Cannot Prove
I consider this one of the most important responsibilities of experienced UX researchers. A useful research report should not merely communicate findings persuasively. It should also identify the limits of its methods and the decisions that remain uncertain.
For example, a formative usability test may support a recommendation to correct an observed interface breakdown. It may not support a claim that the redesign will increase revenue. A survey may reveal reported dissatisfaction among respondents. It may not establish the causal reason for churn. An A/B test may show a difference in one measured outcome without establishing that the winning variant provides a better experience across every relevant task.
Decision-makers should see these limitations as useful information rather than research failure. The purpose of UX research is to improve judgment, not to manufacture certainty.
How to Build a Risk-Based UX Research Plan
I would build a UX research plan by moving from the decision to the required evidence, rather than beginning with a calendar of predefined interviews, tests, and surveys. The plan should describe why each activity is necessary, which claims it may support, and what the team intends to do with the results.
The following sequence can be applied proportionately to small product changes or more consequential design decisions.
- State the decision. Identify what the organization needs to choose, change, preserve, or stop.
- Describe the affected users. Specify the relevant roles, tasks, environments, and access needs.
- Assess decision exposure. Explain the potential consequences, reversibility, and uncertainty of a wrong choice.
- Audit existing evidence. Examine reliable research, support records, product analytics, and documented assumptions before commissioning new work.
- Identify the principal evidence gap. Determine whether the missing information concerns behavior, attitudes, context, prevalence, or the effect of an intervention.
- Select UX research methods. Choose the smallest credible combination of techniques capable of informing the decision.
- Define recruitment and measurement. Specify participants, task conditions, outcome definitions, ethical safeguards, and analytical limitations.
- Identify disconfirming evidence. Establish what finding would challenge the favored explanation or change the proposed decision.
- Report claims with their boundaries. Separate direct observations, interpretations, estimates, and unresolved uncertainty.
- Make the decision traceable. Record the selected action, supporting evidence, responsible owners, and circumstances that would justify reconsideration.
For low-risk work, this sequence can be concise. For consequential decisions, the same reasoning may justify a more detailed protocol and stronger evidence requirements. The framework is intended to help teams choose research deliberately, not to introduce an identical approval process for every interface change.
When Existing Evidence May Be Sufficient
Not every decision requires a new user study. Sometimes the organization already has relevant research, trustworthy behavioral data, or repeated observations collected under sufficiently comparable conditions. Repeating the same investigation can waste resources without meaningfully changing the decision.
I would evaluate whether the existing evidence applies to the current user population, product version, task, and decision context. Old findings are not automatically obsolete, but their relevance should not be assumed merely because they address a similar topic.
Where uncertainty is small and the decision is reversible, proceeding with explicit monitoring may be justified. Where critical risks remain untested, the absence of new research should be a conscious and documented decision rather than the accidental consequence of schedule pressure.
Research Quality Includes Ethics and Participant Protection
Research plans should respect informed participation, appropriate consent, confidentiality, data minimization, and the practical circumstances of the people being studied. Employees and customers may feel pressure to participate when recruitment occurs through organizational authority. Researchers should account for that context rather than assuming participation is automatically voluntary.
I would also consider whether observation, session recordings, support records, or analytics contain sensitive information. The need to understand user behavior does not justify collecting unnecessary personal data or exposing confidential workflows in research reports.
An ethically conducted study is not merely a legal requirement or administrative detail. Participant trust, honest recruitment, and appropriate handling of research data are conditions for producing evidence the organization can responsibly use.
Common Mistakes When Choosing UX Research Methods
Selecting the Method the Team Knows Best
Experienced teams naturally develop preferred tools and routines. Interviews may be easy to organize, analytics may already be available, and unmoderated tests may fit the release schedule. But convenience does not establish method fit. I would question whether the familiar activity can actually resolve the uncertainty attached to the current decision.
Using Surveys to Answer Behavioral Questions
Asking people whether they believe they could complete a task is not equivalent to observing task completion. Surveys are useful for appropriate self-reported constructs, but they cannot substitute for behavioral evidence whenever the decision requires demonstrating what people can do.
Treating a Small Sample as a Universal Statistical Rule
Small qualitative studies can be efficient for discovering interface problems, but they do not automatically support precise estimates of population behavior. Researchers should match sample planning to the intended claim instead of applying the same participant count to interviews, usability benchmarks, and controlled comparisons.
Treating Analytics as Proof of Causation
Recorded behavior can reveal patterns and changes, but the explanation may involve several unobserved conditions. A declining conversion rate does not, by itself, identify a UX defect. A product team should consider instrumentation, user mix, traffic sources, technical performance, and alternative explanations before attributing the change to one interface decision.
Designing Research That Cannot Disprove the Preferred Answer
Research loses value when tasks, interview questions, or success measures make a predetermined solution appear favorable. I would require the team to identify what evidence could challenge its preferred interpretation. A study without a credible disconfirmation path can become an exercise in organizational reassurance.
Generalizing One User Group to the Entire Product
Different roles, abilities, languages, and working contexts can produce materially different experiences. A navigation design that works for experienced administrators may be difficult for occasional users. Research conclusions should remain bounded by the participants and conditions studied, with additional evidence gathered where the decision depends on other populations.
Measuring Research Productivity by Output Volume
The number of interviews conducted, surveys launched, or reports delivered is not a sufficient measure of research contribution. These outputs may be useful operational indicators, but the more important question is whether the evidence improves the team’s understanding of a consequential decision and reveals its remaining limitations.
Evidence and Methodology: What This Framework Establishes
This article is a research-backed methodological analysis, not a completed user study. Its established foundations come from Nielsen Norman Group’s research-method classification, guidance on attitudinal and behavioral evidence, qualitative and quantitative study design, triangulation, and sampling; GOV.UK guidance on planning user research; and W3C accessibility evaluation resources.
These sources support the importance of selecting methods according to research questions, understanding their evidentiary limitations, and combining complementary techniques when the decision justifies additional investigation.
The Decision-Risk Research Fit Framework is my own analytical synthesis. Its decision-exposure categories, four-step method-selection process, and illustrative enterprise administration scenario are proposed decision tools rather than a formally validated industry standard. No controlled comparison has established that applying this framework produces better product outcomes than another research planning approach.
No original participant interviews, usability tests, survey results, analytics exports, accessibility audits, or statistical measurements were conducted for this article. The enterprise navigation scenario and research decision record are hypothetical examples intended to demonstrate how study selection could be structured.
A future evaluation of the framework could compare how different UX teams choose research methods for equivalent decision cases. The assessment could examine whether participants identify the critical evidence gap, select an appropriate method, distinguish unsupported claims, and communicate uncertainty. Such a study would need a defined rubric, appropriate participants, comparable scenarios, and transparent analysis.
Even if the framework improved the quality of research planning, that would not by itself prove improved product outcomes. Research execution, participant quality, organizational decision-making, design implementation, and the product environment would still influence the eventual result.
Frequently Asked Questions About UX Research Methods
What are the main UX research methods?
Common UX research methods include user interviews, usability testing, contextual inquiry, surveys, behavioral analytics, diary studies, card sorting, tree testing, and controlled experiments. These methods investigate different aspects of behavior, attitudes, context, and outcomes. The appropriate choice depends on the research question and the decision it needs to inform.
How do you choose the right UX research method?
Begin by defining the decision, identifying the consequences of being wrong, and determining which evidence is missing. Then select a method that can reasonably provide that evidence. If the question concerns task behavior, observe relevant users performing tasks. If it concerns experiences or motivations, interviews may be appropriate. If it requires a population estimate, design a suitable quantitative study.
What is the difference between user interviews and usability testing?
User interviews primarily explore reported experiences, expectations, motivations, and contextual information. Usability testing observes participants attempting tasks with a product or prototype. The two can complement each other, but descriptions of intended behavior should not automatically be treated as evidence of successful task performance.
When should a team use qualitative versus quantitative UX research?
Qualitative research is particularly useful for identifying problems, exploring behavior, and understanding possible explanations. Quantitative UX research is useful when the decision requires an estimate or comparison of defined measurable outcomes. Study design, sampling, and uncertainty must support the intended inference. Neither category is universally superior to the other.
Can five usability test participants provide enough evidence?
A small qualitative study may identify valuable usability problems and support iterative design improvements. It generally cannot provide precise population-wide estimates of task success or error prevalence. Whether five participants are adequate depends on the research objective, user groups, task variability, and the consequences of the decision.
Are UX surveys reliable for measuring user behavior?
Surveys can provide useful evidence about self-reported experiences, attitudes, and recalled behavior, but they do not directly observe task performance. Their validity also depends on recruitment, question wording, response bias, and the intended population. When actual behavior is central to the decision, observational or behavioral measures may be necessary.
What is research triangulation in UX?
Research triangulation combines different evidence sources or methods to improve understanding of a question. For example, analytics may reveal a repeated abandonment pattern while usability testing helps investigate what happens during the task. The methods should address complementary limitations; simply collecting more data from the same biased source does not guarantee stronger conclusions.
How much UX research is necessary before a product decision?
The required effort depends on the uncertainty, consequences, and reversibility of the decision. Small, reversible changes may justify focused research and monitoring. Consequential decisions affecting critical tasks, multiple user groups, or accessibility may require broader evidence and stronger validation. No fixed research-method quota or participant count applies to every situation.
Conclusion: Good UX Research Begins With the Decision, Not the Method
I believe the quality of UX research is demonstrated less by the sophistication of its tools than by the precision of the questions it answers. A user interview, usability test, survey, or analytics review becomes valuable when it reduces uncertainty about a decision that matters to the people using the product and the organization responsible for it.
Research methods have different strengths because human experience has different dimensions. What people say, what they do, how often something occurs, and why it happens are related questions, but they are not the same question. Treating their evidence as interchangeable can lead teams to make confident claims that their studies cannot support.
The Decision-Risk Research Fit Framework offers one way to make method selection more deliberate. Start with the decision. Understand what being wrong would mean. Identify the evidence that could change the answer. Then choose the research activity capable of providing that evidence with an appropriate level of effort and methodological rigor.
Sometimes a short qualitative study will be enough to support a useful design correction. Sometimes a more comprehensive investigation will be warranted. And sometimes the evidence already available will support moving forward without conducting another study. The right choice is the one the team can justify against the decision’s consequences, not the one that fills a familiar research template.
For UX and product leaders, the objective should not be to run more research by default. It should be to make better-supported decisions, explain what remains uncertain, and recognize when the potential cost of being wrong requires stronger evidence.
That is the standard I would use when choosing UX research methods: not the method I know best, but the method that can most responsibly inform the decision in front of me.
Explore related research, usability, and information architecture topics in the UX & UI Design Articles collection. My broader approach to evaluating digital products is described in UX & UI Design Expertise, and I share professional perspectives through LinkedIn.